

Maximum of 25 job preferences reached.
Top Remote Data Engineering Jobs in Charlotte, NC
Legal Tech • Software • Generative AI
Own Eve’s go-to-market data models and semantic layer for governed metrics including pipeline, conversion, CAC, win rate, ARR, and bookings. Establish certification frameworks, modeling standards, documentation, alerting, and analytical application patterns across the organization. Partner with Sales, Marketing, Customer Success, and RevOps stakeholders, resolve conflicting metric definitions, enable AI-grounded data tools, review contributions, and mentor analytics engineers.
Top Skills:
ApolloClaude CodeClayDbtDealhubHexHubspotMcp ServersOmniSalesforceSnowflakeSQL

Fintech • Real Estate • Software • Financial Services • PropTech
Own Hometap’s product and marketing event-data ecosystem, including taxonomy, tracking plans, governance, Segment Protocols, schema validation, and source management. Partner with marketing, product, and engineering to define instrumentation and event specifications. Build monitoring for schema conformance, event volume, and property completeness, while documenting standards and managing event review and deprecation processes.
Top Skills:
AmplitudeCi/CdCloud Data WarehousesGitGoogle Analytics 4JavaScriptJson SchemaMixpanelPosthogSegmentSegment ProtocolsSQL

Computer Vision • Digital Media • Kids + Family • Mobile • Software • Sports
Staff Data Engineer responsible for setting technical direction, architecting scalable data platforms, leading cross-functional initiatives, improving reliability and performance, and enabling AI-assisted analytics and development. The role includes hands-on development with Python, SQL, cloud data warehouses, orchestration, infrastructure as code, Kubernetes, Kafka, and streaming pipelines, along with mentoring, technical advocacy, documentation, code reviews, and on-call troubleshooting.
Top Skills:
Ai-Assisted Software DevelopmentAirflowAWSAzureBigQueryCloud Data WarehousingDockerGCPInfrastructure As CodeKafkaKubernetesPythonSnowflakeSQLStreaming Data PipelinesTerraform

Automotive • Big Data • Information Technology • Robotics • Software • Transportation • Manufacturing
Staff Data Engineer leading architecture and technical direction for real-time and batch motorsports data platforms. Responsibilities include telemetry ingestion, streaming systems, data quality, observability, cloud platforms, reliability, incident response, technical standards, roadmap planning, stakeholder influence, and mentoring. The role delivers scalable solutions supporting race-day operations and cross-functional analytical products.
Top Skills:
Apache FlinkApache KafkaSparkAWSAzureDatabricksJavaKubernetesPythonScala
Artificial Intelligence • Cloud • Sales • Security • Software • Cybersecurity • Data Privacy
Build and maintain dbt data models, SQL transformations, ingestion pipelines, orchestration, and Tableau dashboards in support of HR and enterprise analytics. Own data quality, metric standardization, privacy controls, Row-Level Security, documentation, CI/CD, and troubleshooting from source systems through reporting. Partner with stakeholders to define requirements and KPIs, support workforce forecasting, optimize BigQuery performance, and pilot AI-assisted analytics using Google Gemini.
Top Skills:
AirbyteApache AirflowCi/CdCloud ComposerDbtFivetranGitGoogle BigqueryGoogle Cloud PlatformGoogle GeminiPythonSQLTableau CloudTableau DesktopTableau Server
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free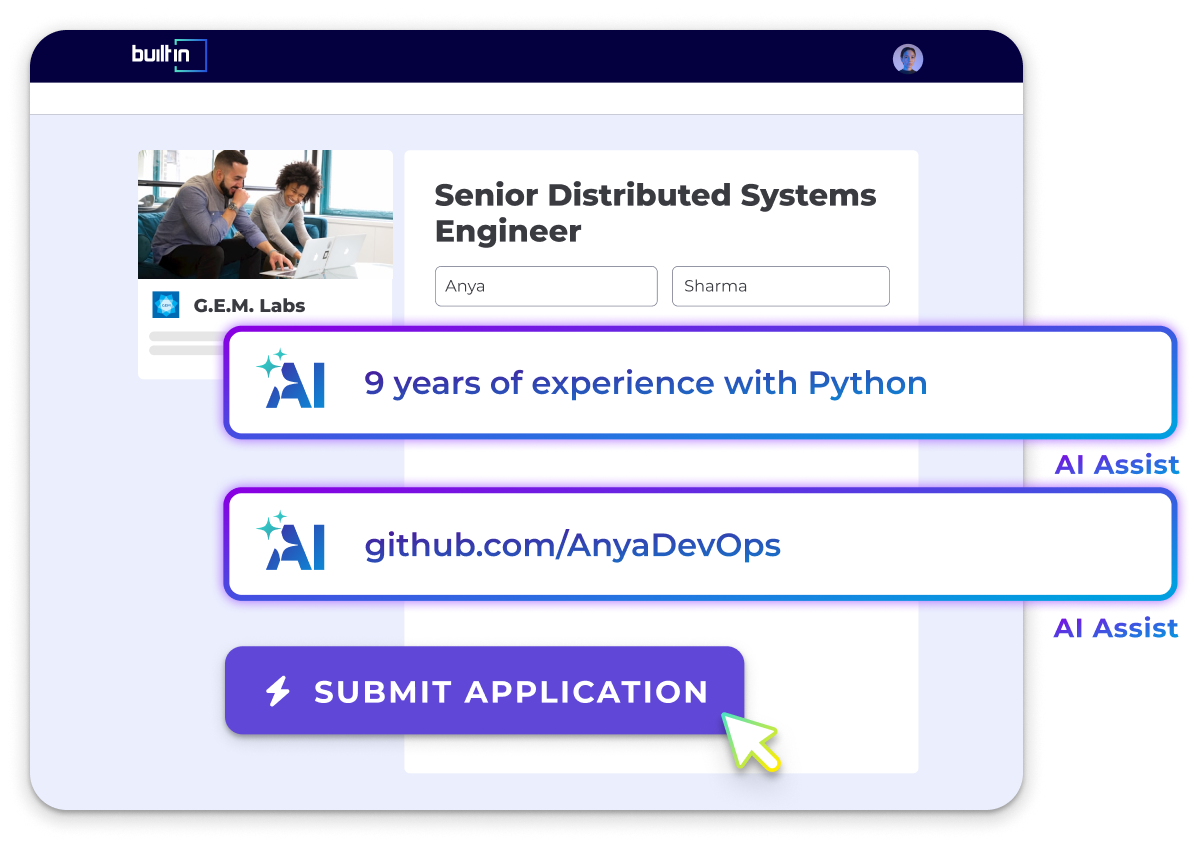
Cloud • Security • Software • Cybersecurity • Automation
Leads an eight-person analytics engineering team and sets strategy for trusted semantic models, governed data, enterprise BI, AI-powered data access, and production data applications. Oversees data modeling, evaluation datasets, telemetry, LLM routing, governance, security, and self-service capabilities. Partners cross-functionally to establish engineering standards, roadmaps, and measurable business impact while hiring, coaching, and developing team members.
Top Skills:
Ci/CdClaudeDbtGitlabGitlab DuoMcp ServersOmniPostgresPythonReactSlack AgentsSnowflakeSQLTableauTypescript

Artificial Intelligence • Big Data • Cloud • Information Technology • Software • Big Data Analytics • Automation
Lead enterprise data architecture across warehouses, data lakes, downstream applications, and AI workloads. Design data models, Medallion Architecture, ELT standards, semantic layers, APIs, access controls, and reusable datasets. Partner with business and BI teams to drive adoption, conduct architecture reviews, establish platform standards, and mentor data and analytics engineers. The role requires deep Snowflake, dbt, data modeling, pipeline, and semantic-layer expertise, with experience in AI data patterns and cloud infrastructure preferred.
Top Skills:
AWSAzureDatabricksDbtDelta LakeGCPGraphQLLlmsPower BIRagRestSnowflakeSnowflake Unity CatalogTableau

Consumer Web • eCommerce • Machine Learning • Software • Sports • Analytics
Build and own scalable data platforms and ingestion pipelines using BigQuery, dbt, and modern ingestion tools. Design batch and CDC workflows, improve reliability and observability, implement governance and access controls, and support analytics and AI agents. Develop Python services and internal tooling, contribute to architecture and lakehouse experiments, collaborate with stakeholders, and mentor engineers. The role requires strong SQL, Python, cloud infrastructure, testing, CI/CD, and AI-assisted development experience.
Top Skills:
Ai Coding AgentsAmazon Web ServicesAPIsCdcCi/CdClaude CodeDbtEstuaryGitGoogle BigqueryGoogle Cloud PlatformHevoLakehouseMcpOpen Table FormatsPythonSQL
Artificial Intelligence • Machine Learning • Natural Language Processing • Software • Conversational AI
Build Deepgram’s governed decision layer above warehouse gold tables. Responsibilities include modeling cross-system entities, owning semantic and metrics definitions, creating agent-facing data tools and MCP surfaces, implementing data quality assertions and reconciliation checks, evaluating AI agent accuracy, and answering business questions while leaving reusable models behind. The role requires production-grade SQL and Python, semantic-layer ownership, strong data modeling judgment, AI-native workflows, clear writing, and comfort building infrastructure from scratch.
Top Skills:
AthenaCubeDbtIcebergLookmlMcpPythonSalesforceSQLStripeTrino

Artificial Intelligence • Cloud • Computer Vision • Hardware • Internet of Things • Software
Build and maintain reliable data pipelines, computed tables, and scalable data models using SparkSQL and PySpark. Integrate IoT, product, customer, external, unstructured, and ML-related data into a central data lake for analytics, causal inference, model training, and dashboards. Ensure high data quality and uptime while collaborating with data science, analytics, AI/ML, and engineering teams.
Top Skills:
Apache AirflowAWSAzureDagsterData LakeData ModelingData PipelinesDatabricksDelta LakeETLGCPGitGitPrefectPysparkPythonRest ApisSparksqlSQL

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top remote Companies in Charlotte, NC Hiring Data & Analytics Roles
See All






All Filters
Total selected ()
No Results
No Results
